Article
How to Submit Your Website to AI
There is no universal AI submission form. Compare search discovery, AI crawler controls, merchant product feeds, and agent integrations by your actual goal.
# How to Submit Your Website to AI
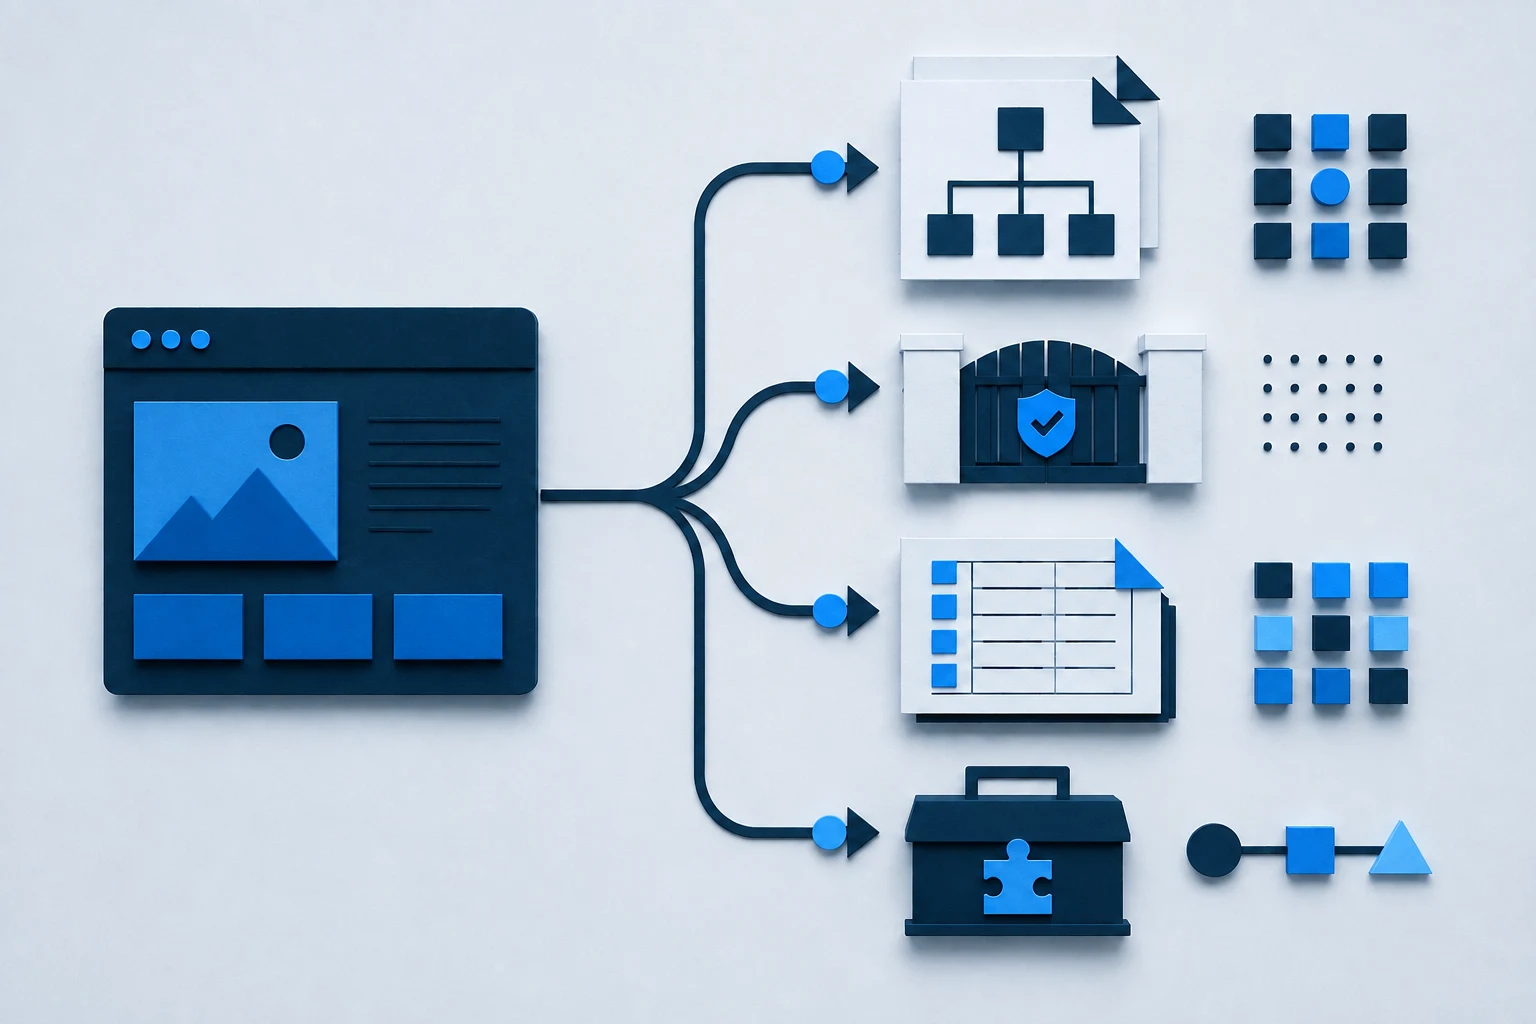
There is no universal form that submits a website to every AI assistant. Choose the route that matches your goal: use search-engine tools and crawler access when you want public pages discovered; use a platform’s merchant feed when you want eligible product data supplied to its shopping surfaces; and build a documented, permissioned integration when you want an agent to perform actions. None of these routes guarantees inclusion, citation, recommendation, traffic, or sales.
An AI assistant may rely on a search index, operate a documented crawler, fetch a user-supplied link, receive a merchant catalog, or call a tool. Sending a sitemap to one company does not enroll the site in all of those systems.
Define the outcome before changing technical controls. For discovery mechanics, see How Does AI Find Your Website?.
Start with the outcome, not the platform name
Write one sentence describing what should become possible. Most requests fall into one of three groups.
| Your goal | Primary route | What it provides | What it does not provide |
|---|---|---|---|
| “I want my public website to be found.” | Crawlable pages, links, sitemap, search-engine tools, service-specific crawler permissions | Paths for discovering and retrieving public URLs | Guaranteed indexing or use in an answer |
| “I want my products to appear in shopping experiences.” | Platform-specific merchant program or structured product feed, supported by accurate product pages | Normalized product and offer data for that platform | Universal distribution to every assistant |
| “I want an agent to do something on my site.” | A documented API, tool, or agent integration with authentication and confirmation | A bounded action such as lookup, quote, reservation, cart, or checkout where supported | Automatic discovery, permission, or safe operation without implementation |
You may need more than one route. A feed can supply price and availability while public pages explain the brand and policies. Keep separate owners, controls, and success measures.
Prepare the website before you notify anyone
Submission amplifies what is already available. Check the public site first so you do not ask a platform to process broken, private, duplicate, or contradictory pages.
Choose canonical URLs for your home page, important categories, products, policies, and contact information. Confirm that each returns a successful response without a login and is reachable through normal links. Remove unintended noindex directives, repair redirect chains, and inspect robots.txt for the exact crawler you intend to support. Keep confidential content behind authentication rather than relying on crawler rules.
Product identity, attributes, price, availability, variants, policies, and seller details should agree with structured data and feeds. Successfully submitting stale facts creates a data-quality problem.
If the store has multiple languages, submit and link the correct localized canonical URLs. Do not send an English page as the finished answer for a Turkish customer merely because the translation is incomplete.
Use search-engine notification for public web discovery
For web discovery, use the webmaster tools of search systems relevant to your audience. Verify ownership, submit the current sitemap, and inspect representative URLs to expose crawl or indexing problems.
Google documents two main recrawl routes: URL Inspection for a small number of URLs and sitemap submission for many URLs. Google also states that a crawl request does not guarantee inclusion and that repeated requests do not make crawling faster. Treat submission as a notification, then monitor the property instead of clicking the button every day.
Keep the sitemap at a stable public URL and reference it in robots.txt when appropriate. Include preferred, indexable URLs rather than filters, account pages, internal results, or duplicates. Also fix internal navigation.
This route does not mean you have “submitted to AI” in general. It improves the chance that a particular search index can discover and diagnose the site. Whether an assistant uses that index, and whether it selects your page for a question, is a separate matter.
Configure documented AI crawler access deliberately
Some AI services publish user-agent names and network information. Review those official documents, decide which purposes you support, and make the smallest intentional change to your crawler and firewall rules. Then verify the result in server or CDN logs.
OpenAI currently distinguishes OAI-SearchBot, GPTBot, and ChatGPT-User. OAI-SearchBot is documented for ChatGPT search crawling. GPTBot concerns content that may be used to improve foundation models. ChatGPT-User may visit a page for certain user-initiated actions and is not the automatic crawler used to determine ChatGPT Search inclusion. One permission is not a substitute for another.
Allowing a crawler is access control, not direct submission. The service decides when to crawl and whether to use retrieved content. A separate training control may not express the same choice about search discovery.
User-agent names, IP ranges, and product behavior can change. Record the source URL, review date, policy owner, and purpose so the configuration can be audited.
Use merchant feeds when the goal is product visibility
A merchant feed is a structured catalog delivered to a specific platform. It normally carries fields such as product identifiers, titles, descriptions, URLs, images, price, availability, and variants. It can give the platform a more controlled and frequently updated view than web crawling alone.
The route is platform specific. Google documents Merchant Center as a way to provide product data directly; it is not required for ordinary Google Search inclusion but is required for some Google shopping surfaces. OpenAI documents a structured product-feed path for ChatGPT commerce, with onboarding currently available to approved partners.
There is no shared feed endpoint. Check eligibility, markets, policies, schema, refresh, and approval for each destination. Keep identifiers stable and reconcile the feed with landing pages and checkout.
This overview stops before ChatGPT field mapping, delivery, or onboarding. Those changing details need a dedicated guide and fresh source review. Choose a merchant route for a supported shopping experience, not merely to make an article crawlable.
Build an agent connection only for a defined action
“Let AI use my website” can also mean that an assistant should search private inventory, request a quote, book a service, add an item to a cart, or complete another task. A sitemap and product feed do not safely create that ability.
An action route must define what the tool does, who may call it, how authorization works, what the user confirms, how errors are handled, and what is logged. Private customer or order data must not become public discovery content.
An API or agent protocol is not an SEO shortcut. It may help an authorized agent complete a task after the relevant experience chooses to use the integration. It does not automatically make the domain crawlable, indexed, or recommended. Keep discovery, catalog distribution, and action permissions as separate workstreams even when one customer journey touches all three.
Follow a goal-based submission workflow
Use this sequence to avoid creating accounts and feeds with no clear owner:
- Name the goal. Choose public discovery, product distribution, or a defined agent action.
- Select representative URLs or records. Start with the home page, one category, several products, and core policies.
- Verify public quality. Check response status, canonical, indexability, visible facts, internal links, language, and structured data.
- Choose one destination. Use that destination’s current official documentation, not a universal checklist.
- Configure access. Update crawler, firewall, or authentication rules only as required for the chosen purpose.
- Notify or connect. Submit the sitemap, request selected recrawls, apply to the merchant program, or implement the bounded tool.
- Validate receipt. Use the platform report, feed diagnostics, verified logs, or integration tests appropriate to that route.
- Reconcile facts. Compare platform data with the public page and checkout, especially price and stock.
- Record limitations. Note approval status, supported markets, quotas, refresh timing, and unresolved errors.
- Measure observations. Track crawl events, indexed URLs, feed acceptance, citations, referrals, or completed authorized actions without claiming causation too early.
If the first route works for the pilot set, expand with repeatable ownership and monitoring. If it fails, diagnose the failing stage before adding another platform.
Avoid these common submission mistakes
The most common mistake is searching for an unofficial directory that promises to “register your site with all AI tools.” A listing may have no relationship with the crawlers, indexes, merchant programs, or integrations used by an assistant. Verify every destination in the platform’s own documentation.
Do not confuse training permission with search visibility, or a search-engine sitemap with merchant enrollment. Do not upload a feed before deciding which system owns price and stock. Do not expose private endpoints simply to make an agent connection possible. And do not resubmit unchanged URLs repeatedly in the hope of forcing an index update.
Finally, avoid reporting a successful submission as a successful outcome. “Sitemap processed,” “crawler allowed,” “feed accepted,” and “tool call passed” are useful technical states. None proves that the site will be cited, recommended, visited, or purchased from.
Frequently asked questions
Is there one place where I can submit my site to all AI assistants?
No shared submission console is documented across the search, crawler, merchant-feed, and agent systems reviewed for this guide. Each destination has its own discovery controls or integration path. Recheck current official documentation before publication or implementation because platform options change.
Can I submit my website directly to ChatGPT?
For web search, OpenAI documents OAI-SearchBot access rather than a universal website-submission form. For commerce, OpenAI documents a separate structured product-feed path whose onboarding is currently limited to approved partners. These are different purposes and neither guarantees appearance in an answer.
Should I submit every page manually?
Usually not. Maintain crawlable internal links and a current sitemap for the preferred public URLs. Use individual recrawl requests for a small number of important new or changed pages when the search engine supports it, and follow its quotas and guidance.
Is submitting a sitemap enough for products to appear in AI shopping results?
No. A sitemap helps with URL discovery. Shopping experiences may require a platform-specific merchant account, feed, eligibility review, policy compliance, and accurate landing pages. Requirements differ by platform and market.
Do I need an API for an AI assistant to read my website?
Not for ordinary public-page discovery. A crawler can retrieve accessible web pages. An API or agent tool becomes relevant when you want a system to query protected or structured data or perform a specific authorized action; it requires its own security and user-control design.
Sources
- Google: Ask Google to Recrawl Your URLs
- Google: Build and Submit a Sitemap
- Google: Introduction to robots.txt
- Google: Share Your Product Data
- OpenAI: Overview of OpenAI Crawlers
- OpenAI: Agentic Commerce — Get Started